Apache Spark
5 blogs · 1 talk
Reading, writing, and ingesting lakehouse tables with Apache Spark.
Apache Kafka (Kafka Connect) vs. Apache Flink vs. Apache Spark: Choosing the Right Ingestion Framework (opens in a new tab)
This article compares three data ingestion frameworks—Kafka, Flink, and Spark—highlighting their unique strengths, use cases, and performance capabilities.
Apache KafkaApache FlinkApache SparkStream ProcessingOctober 3, 2025onehouse.ai
Apache Hudi does XYZ (1/10)
How Hudi's multi-modal index prunes partitions and files so query engines read only the data they need, the first post in a series on Hudi 1.0 features.
Apache HudiIndexingApache SparkJune 16, 2025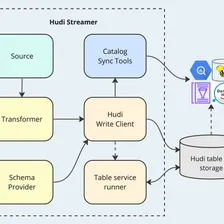
Apache Hudi: From Zero To One (9/10)
Hudi Streamer - a "Swiss Army knife" for ingestion
Apache HudiApache SparkApache KafkaMarch 1, 2024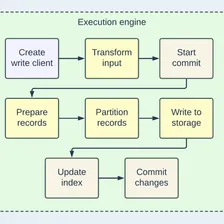
Apache Hudi: From Zero To One (3/10)
How a Hudi write works end to end, from indexing and tagging records to committing files, and the write operations Hudi offers.
Apache HudiApache SparkSeptember 15, 2023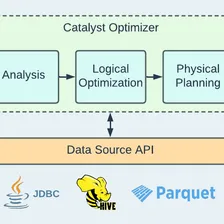
Apache Hudi: From Zero To One (2/10)
How Hudi serves reads: the query planning flow in Spark, and the snapshot, read-optimized, time travel, and incremental query types.
Apache HudiApache SparkIncremental ProcessingSeptember 6, 2023